YPOG AI Workshop: Legal, Fund & Finance
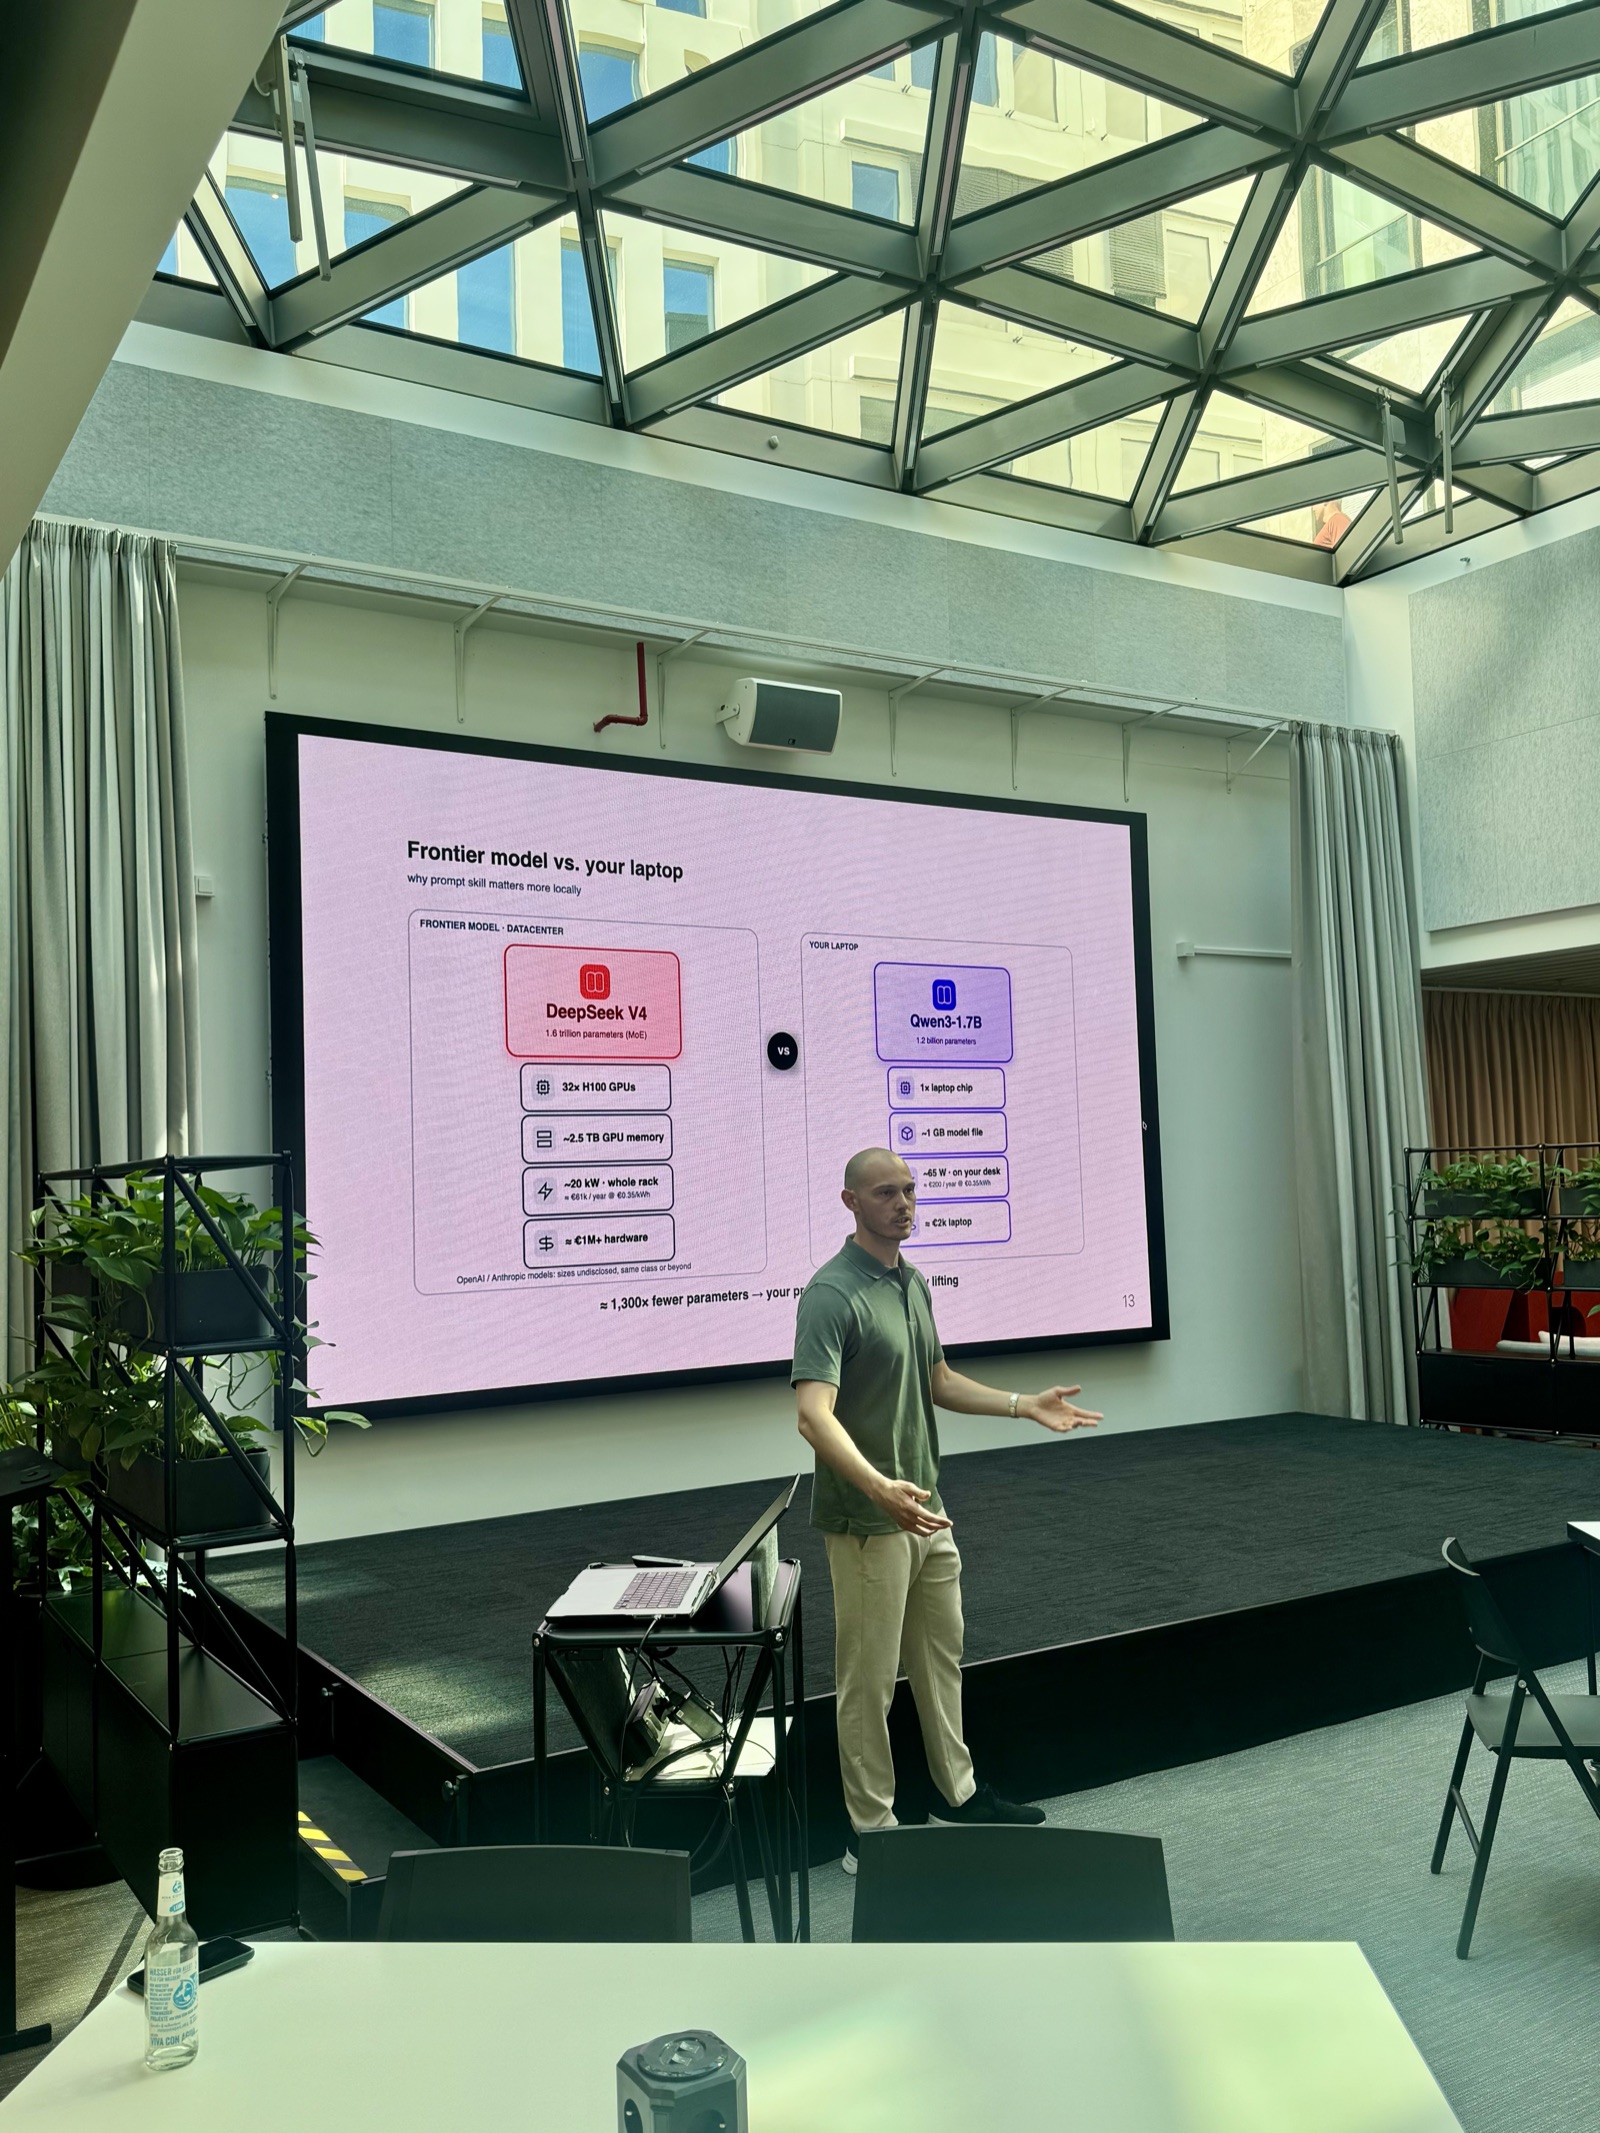
On 17 June 2026 I ran a hands-on AI workshop for legal and finance practitioners at YPOG. The theme: build a local, citation-grounded AI assistant over fund documents, where no data leaves the laptop. Thanks to YPOG for hosting the workshop and bringing a curious, well-prepared group into the room.
What we covered
- What AI models are: inference as one pass per token, training as billions of next-token guesses with weight corrections. Different model types (chat, embedding, vision, reasoning) and what they are good for.
- Why local AI: professional secrecy, GDPR and client mandates on the legal side. Cost, version control and offline use on the practical side. We looked at three cases where cloud AI went wrong: a frontier model pulled globally overnight, an exposed chat-log database, and shared chats indexed by Google. Local AI is the simplest defensible answer to “where is my data processed?”.
- Prompt patterns: zero-shot vs. few-shot, chain-of-thought, and why prompt skill matters more with a small local model than with a frontier one.
- RAG (Retrieval Augmented Generation): chunking, embeddings, similarity search, retrieval, and injecting the matched chunks into the prompt so answers stay grounded in the source text with citations.
Hands-on
Every participant set up a complete local RAG stack on their own laptop, from a USB kit:
- LM Studio runs the models and serves them at
localhost:1234 - AnythingLLM embeds the PDFs, retrieves matching chunks and handles the chat
- Qwen3 (1.7B / 4B / 14B, Q4_K_M) as chat model, picked by available RAM, and bge-m3 for embeddings
The corpus was a fictional fund, Team Rocket Opportunities Fund I LP, with 16 synthetic documents: LPA, side letters, KYC packs, quarterly reports, audit findings, compliance and operations manuals, IC minutes. Participants embedded the documents, set a system prompt, and then asked questions such as who the LPs are, when the next capital call is due, or which investor has a sanctions match. The point was to see which questions pass, which fail, and why. The corpus is fictional and not published.
Material
- Slides (PDF)
- Cheat sheet (PDF): decoding model names, reading a model card, quantization, prompt patterns, glossary, links
Further reading
- LM Studio and LM Studio docs
- AnythingLLM and AnythingLLM docs
- Hugging Face models, filter by GGUF
- lmstudio-community on Hugging Face: curated GGUF builds, including Qwen3
- bge-m3 GGUF: the embedding model used in the workshop
- LM Arena: community model leaderboard
- OpenRouter: one API for many cloud models, for comparison only, not for confidential data
- Incidents mentioned in the slides: Euronews on the Fable 5 shutdown, Wiz on the DeepSeek database leak, TechCrunch on indexed ChatGPT chats
 Alexandros Sivris
AI product discovery